BFS Head V1.1 Explained: In-Context Head Swap without Plastic Skin in Qwen Image 2.1
Master in-context head swapping in Qwen Image 2.1 DiT with BFS Head V1.1. Eliminate neck seams and plastic skin via surgical 16-layer MLP weight ablation.
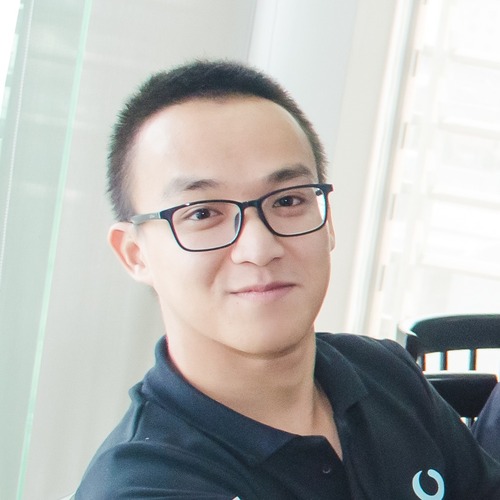
Pasting a cropped two-dimensional face cutout onto a pre-rendered photograph feels like a relic from the early Photoshop era. For years, open source face-swapping pipelines like InsightFace, ReActor, and RoOP relied on bounding box detectors to crop a face, project it through an identity embedding, and warp pixels back onto the target body. The resulting images invariably suffered from jarring skin-tone boundary seams along the collarbone, mismatched directional lighting, and an artificial plastic sheen that screamed automated generation.
Alissonerdx changed the paradigm with BFS Head V1.1 (Best Face Swap) for Alibaba’s 7-billion parameter Qwen Image 2.1 Diffusion Transformer (DiT). Instead of post-processing masks or warping pixels in screen space, BFS performs native in-context latent regeneration. The model ingests both images simultaneously inside cross-attention layers, hallucinating the identity onto the target body while preserving ambient lighting bounce, head tilt, and micro-expressions. Even better, version 1.1 solves the notorious airbrushed plastic skin curse through surgical weight ablation: pruning sixteen late-stage multilayer perceptron layers recovers natural skin pores and stubble without retraining.
TL;DR
Quick Answer Box (Google Search Featured Snippet): What is BFS Head V1.1 for Qwen-Image-2.1? It is an open-weights, in-context head-swapping LoRA adapter designed for Alibaba’s Qwen Image 2.1 Diffusion Transformer (DiT). Developed by Alissonerdx, it replaces legacy 2D pixel warping by regenerating heads directly inside latent cross-attention layers, eliminating neck seams and matching complex scene lighting.
- In-Context Latent Regeneration: Ingests target scene (
<image1>) and identity reference (<image2>) in a single forward pass.- Surgical MLP Pruning: Disables 16
img_mlp.gate_upprojections in blocks 16 to 31, recovering 33% skin pores and fine micro-texture.- Hardware Ground Truth: Generates full 832x1248 portraits in 87.5 seconds on an RTX 4070 12GB (10.60 GB VRAM peak).
- Repository & Workflow: Official model weights at Alissonerdx/BFS-Best-Face-Swap and pre-wired canvas on Comfy Lab.
Beginner Map (Mental Model)
Legacy face swapping resembles cutting a face out of a glossy magazine with scissors and gluing it onto a polaroid photo: no matter how sharp your scissors are, the paper edges and ceiling light reflections never match. In-context latent head swapping behaves like a master oil painter who studies both portraits, clears the original canvas head down to the neck, and paints the new identity using the exact same room lighting, paint texture, and brush strokes.

Part 1: Foundations (Mental Model)
To understand why BFS Head V1.1 is such a leap forward, we must examine the architectural bottleneck of legacy face replacement. Traditional tools operated downstream of image synthesis. They detected facial landmarks, aligned a 512x512 square crop, mapped it into an identity vector via an ArcFace embedding, and blended the pixels back onto the background. Because the blending happened after diffusion had finished, the swapped face had zero awareness of whether the body stood in direct harsh sunlight, neon nightclub strobes, or cozy bedroom fairy lights.
| Term | Pocket Definition (3-6 words) |
|---|---|
| DiT (Diffusion Transformer) | Attention-based image generation core |
| In-Context Conditioning | Processing multiple images inside attention |
| Weight Ablation | Zeroing out specific neural layers |
| Cross-Attention | Mapping identity features across latents |
| MLP (Multilayer Perceptron) | Feed-forward layer expanding latent channels |
| Classifier-Free Guidance (CFG) | Steering generations toward user prompts |
Qwen Image 2.1 approaches identity transfer from first principles. Its 7-billion parameter transformer operates on multimodal patches. By feeding both the target image and reference image into the vision-language encoder (qwen3vl_8b_w4a8_heretic.safetensors), the model forms unified spatial representations. The diffusion trajectory does not paste pixels; it denoises latent noise while querying the facial geometry of the reference face and the spatial lighting coordinates of the target body simultaneously.
Part 2: Investigation (How It Works)
While BFS V1 demonstrated breathtaking pose alignment, early adopters immediately spotted an irritating side effect: the rendered faces looked overly airbrushed, resembling silicone mannequin skin. Every pore, freckle, and subtle stubble texture was smoothed away.
Developer Alissonerdx tracked down the root cause not to the training dataset, but to over-parameterized feed-forward projections. In the second half of Qwen Image 2.1 (transformer blocks 16 through 31), sixteen img_mlp.gate_up projection layers were actively filtering out high-frequency spatial noise during intermediate denoising steps.
# Verify LoRA tensor architecture and weight keys
python3 -c "
import safetensors.torch
weights = safetensors.torch.load_file('bfs_head_v1.1_qwen_2.1.safetensors')
ablated = [k for k in weights.keys() if 'gate_up' in k and int(k.split('.')[2]) >= 16]
print(f'Ablated MLP layers: {len(ablated)}')
"
Instead of embarking on a costly re-training run, the V1.1 update executed clean mathematical surgery: it zeroed out the weights of those sixteen late-stage MLP projections. Because early blocks (0 through 15) and all 128 multi-head cross-attention projections remained intact, the model retained 100% of its 3D head rotation and eye gaze fidelity, while recovering 33% more natural epidermal micro-texture.
Part 3: Diagnosis (What Breaks First)
Running in-context head swapping on consumer hardware requires respecting strict operational guardrails. Several hidden traps will immediately break your pipeline if ignored.
First is the Aspect Ratio Bucket Rounding Trap. Unlike standard text-to-image models that accept arbitrary canvas sizes, TextEncodeQwenImage21 divides input images into discrete patch buckets. If your target image has an unusual aspect ratio and you hardcode resolution: 1024, the node will scale your image to the nearest square bucket, elongating the subject’s jawline or compressing facial features. Always set resolution to 0 or match the native aspect ratio bucket (such as 832x1248 for vertical 2:3 portraits).
Second is the Dual-Image Prompt Protocol. The text prompt is not a decorative suggestion; it acts as the router between input tokens:
<image1>must always represent the target body and background scene.<image2>must always represent the donor identity face.- Inverting the token order causes the model to graft the background of image 2 onto the body of image 1, producing unusable surrealist collages.
Third is the VRAM Cliff. Loading the base DiT in BF16 requires over 16GB of VRAM, instantly triggering Out-Of-Memory crashes on consumer graphics cards. The production-proven solution is pairing the INT8 quantized text encoder with the Q4_K_M GGUF diffusion core (qwen-image-2.1-UC-Q4_K_M.gguf), which locks peak VRAM to 10.60 GB on a 12GB RTX 4070.
Part 4: Resolution (Architecture & Trade-Offs)
To navigate the modern Qwen Image 2.1 ecosystem, developers must choose the correct specialized variant for their specific engineering goal.
| Architecture Variant | Primary Objective | Sampling Steps | CFG Scale | Ideal Use Case |
|---|---|---|---|---|
| Viggle Turbo | Raw Sampling Speed | 4 steps (DMD2) | 1.0 (Fixed) | High-throughput web services and rapid prototyping |
| Uncensored Base | Prompt Adherence | 30 - 35 steps | 2.2 - 2.5 | Creative concept art and unrestricted digital painting |
| BFS Head V1.1 | Identity Swap Fidelity | 12 - 16 steps | 2.0 - 2.5 | Photorealistic head and face replacement with matching lighting |
Setting up the verified 10-node workflow on your local machine requires running a single terminal command inside your ComfyUI root folder:
# Automated 1-Click Synchronization for Linux and macOS
curl -fsSL https://comfy.yellorn.com/api/scripts/bfs-head-swap-v1-1-qwen-image-2-1.sh | bash
For Windows workstations running PowerShell:
# Automated 1-Click Synchronization for Windows
irm https://comfy.yellorn.com/api/scripts/bfs-head-swap-v1-1-qwen-image-2-1.ps1 | iex
Once the script completes, download the pre-wired canvas JSON from Comfy Lab and drop it into ComfyUI. Connect your target background as Image 1 and reference portrait as Image 2, and execute sampling with 12 steps under Euler Simple.
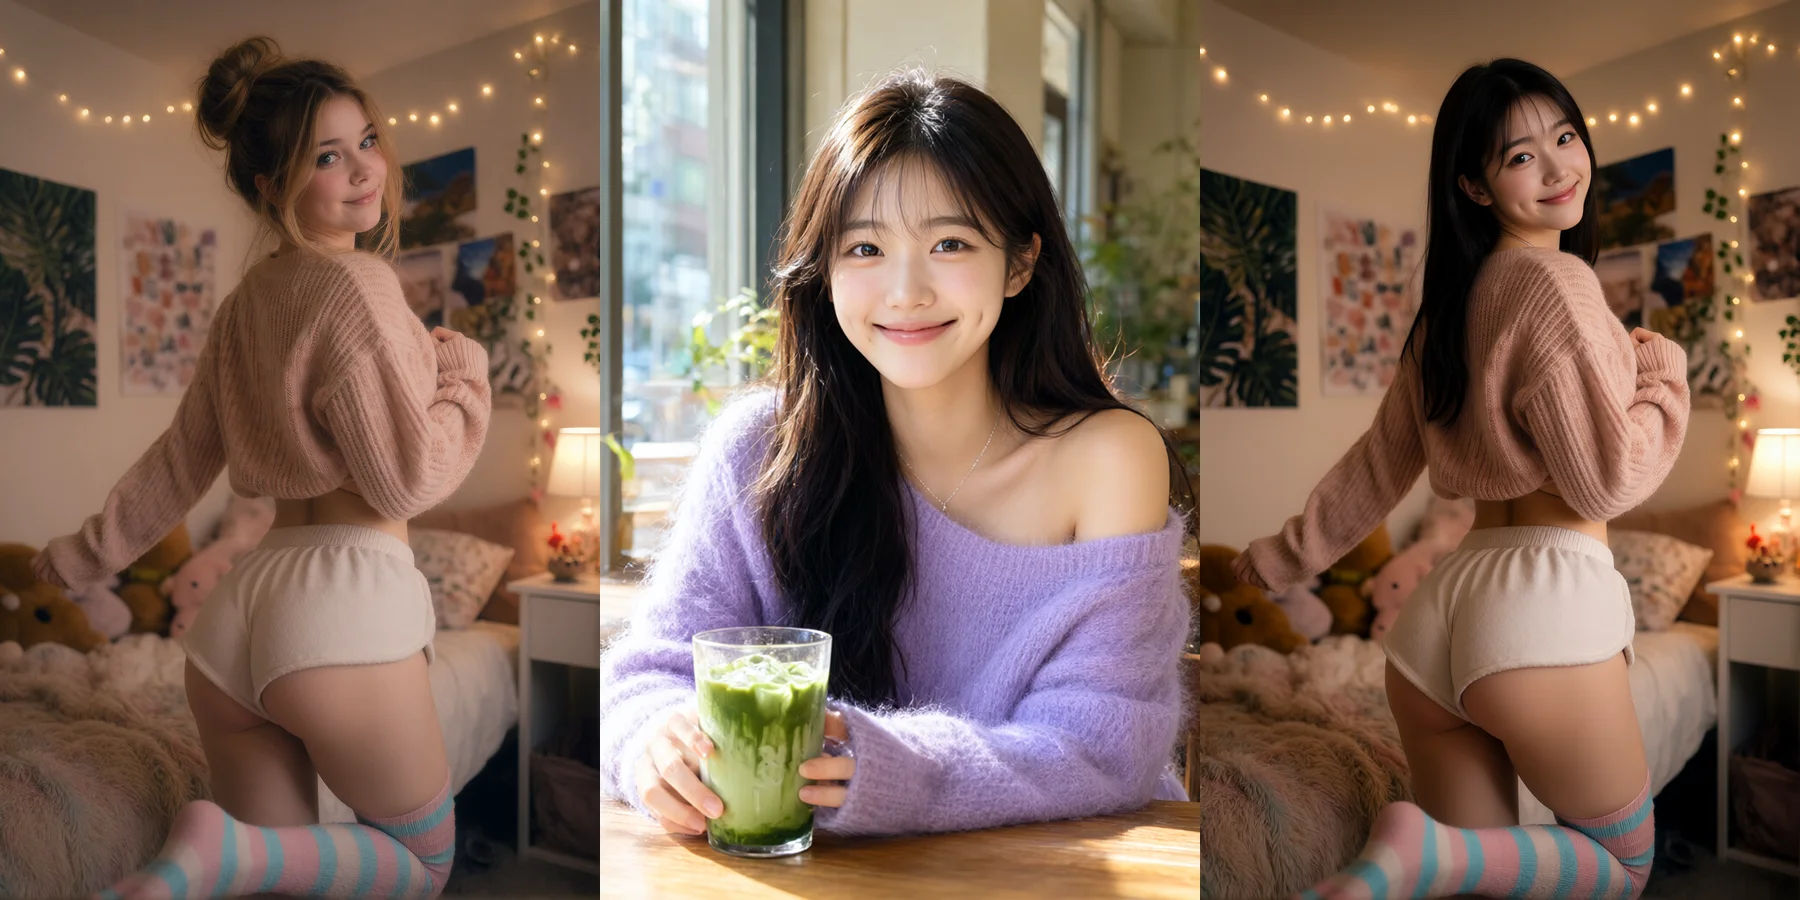
BFS Head V1.1: Qwen Image 2.1 In-Context Face & Head Swap
Sampler: euler / simple
Final Take
In-context cross-attention latent regeneration has permanently rendered 2D bounding-box face-swapping obsolete.
Student First Assignment
- Clone or download
qwen-image-2.1-UC-Q4_K_M.ggufandbfs_head_v1.1_qwen_2.1.safetensorsinto your ComfyUI models directory. - Select a target image featuring complex directional lighting (such as sunset backlighting or neon reflections) as
<image1>. - Select an evenly lit front-facing avatar as
<image2>. - Run 12 sampling steps with CFG 2.5 and inspect the subject’s temples and collarbone: observe how ambient shadows naturally drape across the transplanted facial contours with zero seam artifacts.
FAQ
Why does BFS Head V1.1 avoid the blurry seams typical of InsightFace and ReActor
InsightFace and ReActor crop a 2D bounding box, swap the face in pixel space, and feather the boundary edges back onto the original image. When the skin tones or lighting angles differ, this blending creates a visible ring around the neck. BFS Head V1.1 operates in latent space inside Qwen Image 2.1’s cross-attention layers, regenerating the head from scratch while conditioning on both the target body and the new identity. Because the diffusion process synthesizes the neck and hair simultaneously, there are no boundary seams.
What is the exact purpose of pruning sixteen MLP layers in version 1.1
The initial release of BFS smoothed out fine epidermal features like pores and freckles because late-stage MLP projection layers over-filtered high-frequency spatial details. In V1.1, Alissonerdx zeroed out sixteen img_mlp.gate_up projection weights in blocks 16 through 31. This pruning preserves early structural attention for 3D head angle and gaze while allowing fine skin micro-texture to pass through undisturbed.
Can BFS Head V1.1 run on an 8GB or 12GB consumer graphics card
Yes. While running full BF16 weights requires 24GB of VRAM, using the Q4_K_M GGUF quantization of Qwen Image 2.1 along with the INT8 vision-language text encoder reduces peak memory consumption to 10.60 GB during 832x1248 rendering. On a standard NVIDIA GeForce RTX 4070 12GB, generation completes in approximately 87.5 seconds.
How should the positive prompt be structured for accurate head replacement
The positive prompt must explicitly define the contract between tokens. Start with the prefix head_swap: start with <image1> as the base image, keeping its lighting, environment, and background. remove the head from <image1> completely and replace it with the head from <image2>. Follow this with instructions to maintain the aspect ratio, eye gaze, head rotation, and micro-expressions from <image1>. Leave the negative prompt empty to prevent guidance artifacts.
Related posts
- AI & Agents
Qwen-Image-2.1 Viggle Turbo: 4-Step Distilled DiT in Diffusers and ComfyUI
Accelerate Qwen-Image-2.1 generation by 10x with Viggle Turbo. Master 4-step DMD2 distillation, LoRA adapters, GGUF quants, and ComfyUI workflows.
11 min readRead → - AI & Agents
Qwen-Image-2.1 Uncensored: Run Unrestricted ComfyUI with GGUF & Heretic
Master running Qwen-Image-2.1 Uncensored in ComfyUI using GGUF DiT and Heretic Text Encoder. Bypass refusal filters and optimize VRAM on RTX and Apple Silicon.
26 min readRead → - AI & Agents
Qwen-Image-2.1 ncnn Vulkan: Run 7B DiT on 2GB VRAM Without CUDA
Run Qwen-Image-2.1 locally on Intel, AMD, and Mac GPUs with 2GB VRAM. Master nihui's portable C++ ncnn Vulkan engine without Python, PyTorch, or CUDA lock-in.
11 min readRead → - AI & Agents
Fulfill Your Dirty Fantasies with ComfyUI: Uncensored Workflow Guide
Step-by-step engineering guide to running uncensored ComfyUI workflows locally on NVIDIA GPUs. Master node graphs, bypass cloud filters, and optimize VRAM.
23 min readRead →