Khoj AI: What It Is, Self-Host Personal Second Brain & Setup Guide
Khoj AI: self-hosted second brain for devs. Index Obsidian, Notion and PDFs, chat with local LLMs via Ollama, and run autonomous agents - 100% private.
TL;DR
Quick Answer Box (Google Search Featured Snippet):
- What is Khoj (Khoj AI)? Khoj is an open-source self-hosted AI second brain application (
khoj-ai/khoj) that indexes local markdown notes (Obsidian), Notion docs, and PDFs into a local vector store and connects seamlessly to local LLMs (via Ollama) or cloud AI APIs.- Why Khoj stands out: Unlike standard chatbots that are completely stateless, Khoj features long-term stateful memory and an automated RAG pipeline with precise file-level source citations.
- Fastest Setup: Install via
pip install khoj && khoj runor run the official Docker container:docker run -p 42110:42110 ghcr.io/khoj-ai/khoj.- Official Repository: khoj-ai/khoj on GitHub.
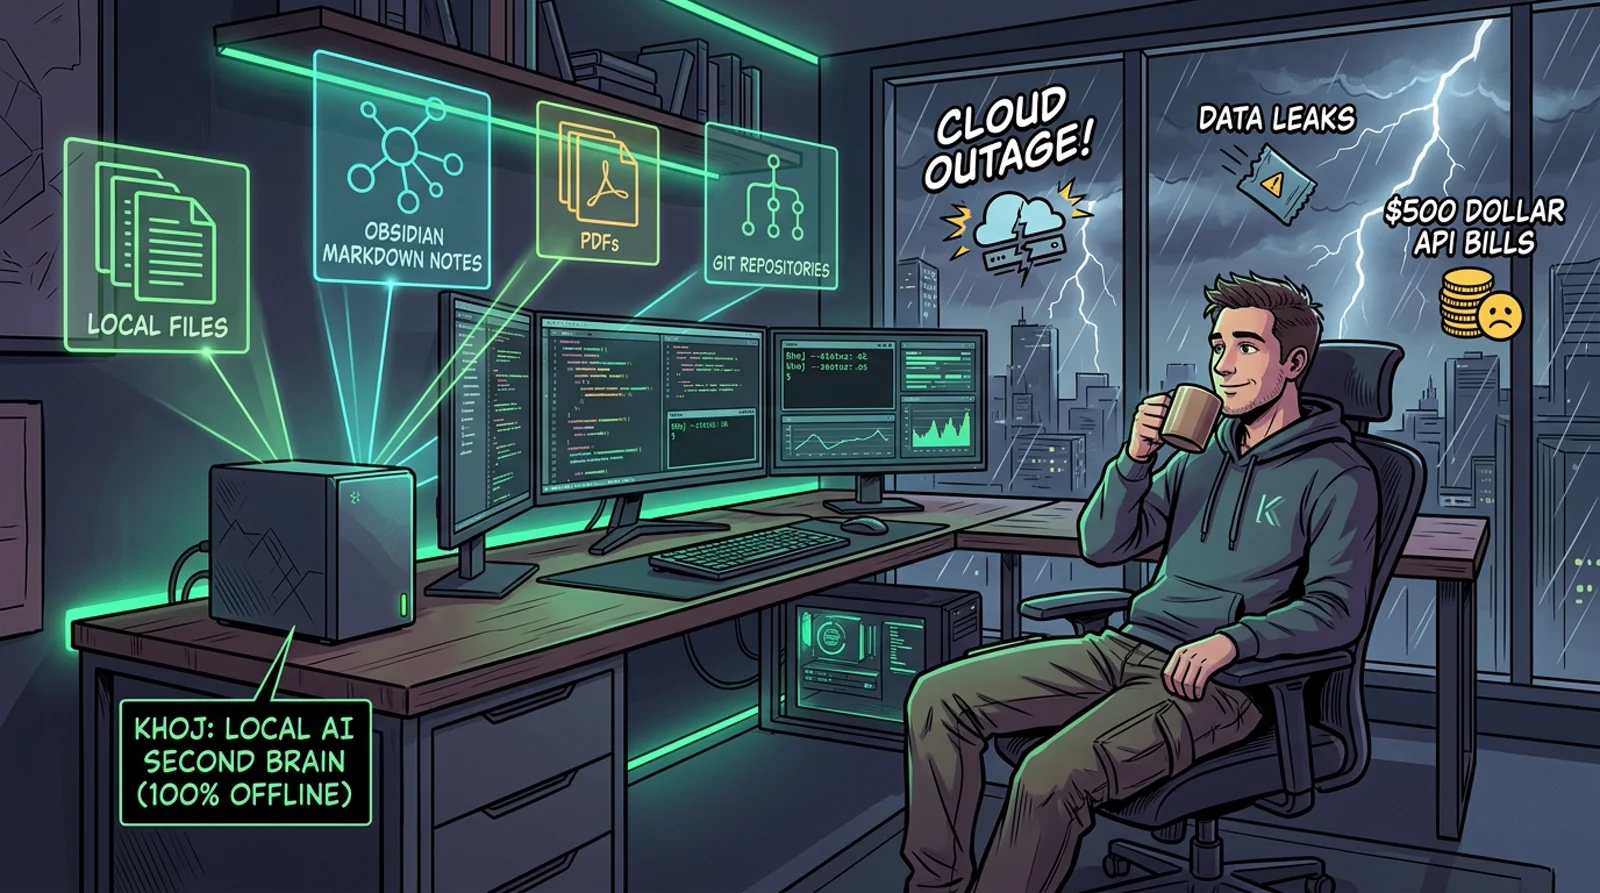
If you are juggling fragmented notes across Obsidian, Notion, and scattered PDFs while copying context into ChatGPT or Claude by hand, Khoj solves that friction. It is a self-hostable, open-source AI second brain that indexes your documents, connects to local or cloud LLMs, and acts as an autonomous knowledge assistant.
- Who it is for: Developers, researchers, and power note-takers who want an AI that retains context across their private files.
- Why it matters: Zero vendor lock-in. Run it locally with Ollama (Llama, DeepSeek) or route to OpenAI/Claude with complete privacy control.
- When to skip it: You only need quick one-off answers and have no personal notes or documents to search.
Beginner Map
The 3-Minute Fast Path: Self-Host Your Second Brain
- Install Khoj: Run
pip install khoj && khoj runor launch via Docker:docker run -d -p 42110:42110 ghcr.io/khoj-ai/khoj. - Connect Local LLM: Launch Ollama (
ollama run llama3.2) or provide your cloud API key inhttp://localhost:42110. - Index Your Vault: Sync your Obsidian markdown vault or Notion workspace.
- Query Private Knowledge: Ask complex multi-document questions with verified source citations. Compare with Defuddle for clean web article extraction and Project Nomad for offline knowledge bunkers.
Read this breakdown in four stages:
- Pass 1: Part 1: Foundations and the stateful memory mental model.
- Pass 2: Part 2: Architecture deep dive, vector stores, and multi-client ingestion.
- Pass 3: Part 3: Real-world developer use cases (research and custom agents).
- Pass 4: Part 4: 5-minute quickstart via pip or Docker Compose.
| Term | Question it answers |
|---|---|
| Second Brain | How does an AI retain memory across thousands of documents? |
| FastAPI Backend | What coordinates semantic indexing, search, and clients? |
| Vector Index | How does Khoj perform instant semantic similarity lookup? |
| Local LLM | How do I chat with notes 100% offline via Ollama? |
| Custom Agent | How do I build a specialized persona with its own docs? |
Student First Assignment
Spin up Khoj on your workstation in under 30 minutes:
- Run
pip install khojor spin up the official Docker container. - Index a local markdown folder containing 5 to 10 technical notes.
- Ask Khoj a question that requires cross-referencing information between two separate files and observe the retrieved citations.
Part 1: Foundations - The Mental Model
You probably have notes scattered across Obsidian, Notion, PDF research papers, and markdown files. You switch between ChatGPT, Claude, and Gemini tabs, pasting context in by hand. You want an AI that already knows everything you know - but all the big players lock your data into their cloud.
That is exactly the gap Khoj is built to fill.
Mental Model: Think of Khoj as a personal AI brain running on Rails: not a chatbot, but an always-on knowledge assistant that has read every document you have ever written, can search the internet, can create autonomous agents, and can do all of this either on your own machine or on Khoj’s cloud, at your choice.
Where most AI tools are stateless (each conversation starts empty), Khoj is stateful and knowledge-indexed. It is your AI that remembers.
Part 2: The Investigation - Architecture Deep Dive
The Big Picture
Khoj is a full-stack Python application built on FastAPI at the core.
Architectural model of Khoj second-brain RAG orchestration and semantic retrieval:

Source Code Structure
Khoj’s codebase under src/khoj/ is cleanly organized by concern:
| Directory | Purpose |
|---|---|
routers/ |
FastAPI REST & WebSocket endpoints (chat, agents, search, files) |
processor/conversation/ |
LLM adapter per provider (OpenAI, Anthropic, Google, Ollama) |
processor/content/ |
Document parsers (PDF, Markdown, Notion, Org-mode, Word) |
database/ |
Django ORM models - conversations, agents, files, users |
search/ |
Semantic search pipeline using sentence-transformers |
routers/api_agents.py |
Full REST API for creating and managing agents |
LLM Adapter Pattern
One of Khoj’s most elegant design choices is the LLM adapter pattern. Each provider gets its own module with the same interface:
# src/khoj/processor/conversation/anthropic/anthropic_chat.py
async def converse_anthropic(
    messages: List[ChatMessage],
    model: Optional[str] = "claude-3-7-sonnet-latest",
    api_key: Optional[str] = None,
    deepthought: Optional[bool] = False,
    tracer: dict = {},
) -> AsyncGenerator[ResponseWithThought, None]:
    """Converse with user using Anthropic's Claude"""
    async for chunk in anthropic_chat_completion_with_backoff(
        messages=messages,
        model_name=model,
        temperature=0.2,
        ...
    ):
        yield chunk
The same pattern is replicated for openai_chat.py, google_chat.py, and ollama_chat.py. The router picks the right adapter at runtime based on the user’s configured model - you swap from GPT-4o to Gemini to Llama 3 without changing any application code.
Document Ingestion Pipeline
Khoj reads your knowledge base and indexes it into a vector store for semantic retrieval:
- PDF →
pypdfparser - Markdown / Org-mode → Plain text extraction
- Notion → Official API integration
- Word → Office XML parser
- Images → Vision LLM description
Everything lands in an embedding vector index (sentence-transformers). When you ask a question, Khoj performs semantic similarity search over your corpus, retrieves the top-k relevant chunks, and passes them as context to the LLM - classic RAG, but deeply integrated.
Part 3: The Diagnosis - What It Does for Developers
Use Case 1: Personal Research Assistant
Load your entire research library - 300 PDFs, 1,000 Markdown notes, every Notion page - and chat with it:
# Sync a local folder of docs
khoj --content-file /path/to/research/

# Or via the web UI: Settings → Files → Upload
Ask: “Which of my papers mentions transformer-based architectures for time-series forecasting?” Khoj retrieves the relevant sections, cites them, and synthesizes a coherent answer.
Use Case 2: Custom AI Agents
Khoj’s agent system lets you create specialized AI personas with their own knowledge base, LLM, system prompt, and tools:
Settings → Agents → Create Agent
- Name: "Python Code Reviewer"
- Model: Llama 3.1 70B (local via Ollama)
- Knowledge Base: your company's internal codebase docs
- Tools: Web Search, Code Execution
- Persona: "You are a strict senior engineer. Review code for security and correctness."
Each agent gets its own chat endpoint. You could have a “Research Analyst” agent reading academic PDFs and a “Marketing Copywriter” agent reading brand guidelines - both running on the same Khoj server.
Use Case 3: Autonomous Research (Scheduled Jobs)
Khoj can act as a proactive assistant:
- Set up a daily automated research task: “Every morning, search for news about AI safety and send me a summary newsletter”
- It browses the web, synthesizes information, and delivers it to your configured channel (email, webhook, etc.)
Use Case 4: Local-First Privacy
For developers who refuse to send data to third-party clouds:
# Run Llama 3 locally via Ollama
ollama run llama3.1

# Point Khoj to it
# In Khoj UI → Chat Models → Add Model → host: http://localhost:11434
Your documents stay on your disk. Your conversations are processed locally. Zero data leaves your machine.
Supported LLMs at a Glance
| Type | Provider | Example Models |
|---|---|---|
| Cloud | OpenAI | GPT-4o, o3-mini |
| Cloud | Anthropic | Claude 3.7 Sonnet |
| Cloud | Gemini 1.5 Pro, Flash | |
| Cloud | Cohere, Mistral AI | Command R, Mistral Large |
| Local | Ollama | Llama 3.1, Qwen, Gemma, DeepSeek |
Part 4: The Resolution - How to Get Started
Option A: Cloud (Zero Setup)
The fastest path - just go to app.khoj.dev and create a free account. No installation needed.
Option B: Self-Host with Docker (Recommended)
mkdir ~/.khoj && cd ~/.khoj

# Download the official compose file
wget https://raw.githubusercontent.com/khoj-ai/khoj/master/docker-compose.yml

# Start everything
docker-compose up -d
Open http://localhost:42110 and you’re in.
Option C: Self-Host with pip (Python Developers)
# Install with local LLM support (llama-cpp-python)
python -m pip install 'khoj[local]'

# Start the server
khoj
For GPU acceleration:
# NVIDIA CUDA
CMAKE_ARGS="-DGGML_CUDA=on" FORCE_CMAKE=1 python -m pip install 'khoj[local]'

# Apple M1/M2/M3
CMAKE_ARGS="-DGGML_METAL=on" python -m pip install 'khoj[local]'
Add Your Knowledge Base
After starting Khoj:
- Web App: Go to Settings → Files → drag-and-drop your PDFs, Markdown files, or connect Notion
- Obsidian Plugin: Install the Khoj plugin → it indexes your vault automatically
- CLI sync:
khoj --content-file ~/notes/ --content-file ~/research/*.pdfConnect Your Preferred LLM
In Settings → Chat Models:
- Add your OpenAI key for GPT-4o
- Add your Anthropic key for Claude
- Point to
http://localhost:11434for Ollama local models
Khoj will route all conversations through whichever model you designate as default.
Final Take
┌────────────────────────────────────────────────────────────┐
│                          Khoj                              │
│                                                            │
│  "Your open-source AI second brain"                        │
│                                                            │
│  What it IS:                                               │
│  → A self-hostable personal AI app (FastAPI + Python)      │
│  → An LLM-agnostic router (GPT, Claude, Gemini, Ollama)    │
│  → A RAG pipeline over YOUR documents                      │
│  → An agent builder with custom knowledge + tools          │
│                                                            │
│  What it SOLVES:                                           │
│  → Knowledge fragmented across files, apps, and tools      │
│  → Dependency on closed, cloud-only AI services            │
│  → Privacy: your data stays on your machine if you want    │
│                                                            │
│  What it ENABLES:                                          │
│  → Chat with 1,000s of your own documents                  │
│  → Local LLMs (Llama, Qwen, DeepSeek) via Ollama          │
│  → Autonomous agents that research and deliver newsletters  │
│  → Multi-platform: Web, Obsidian, Emacs, Phone, WhatsApp   │
│                                                            │
│  Self-host: pip install khoj | docker-compose up           │
│  Cloud: app.khoj.dev (free tier available)                 │
└────────────────────────────────────────────────────────────┘
Khoj bridges the gap between private offline knowledge and modern LLM capabilities. If you want your notes to actively assist your daily workflow rather than rot in cold storage, self-hosting Khoj is a high-leverage move.
GitHub: khoj-ai/khoj
Docs: docs.khoj.dev
Live App: app.khoj.dev
Khoj Frequently Asked Questions (FAQ)
1. What is Khoj and who is it for?
Khoj is a free, open-source self-hosted AI second brain built on FastAPI and Python. It is designed for developers, researchers, and power note-takers who want an AI assistant that reads and remembers their own documents - Obsidian vaults, Notion pages, PDFs - and answers questions with cited sources. Unlike generic chatbots, Khoj is stateful: it retains memory across conversations.
2. How do I install Khoj locally?
Three options: (1) Fastest: pip install khoj && khoj to spin up the server on http://localhost:42110. (2) Docker: docker run -d -p 42110:42110 ghcr.io/khoj-ai/khoj for a zero-dependency container. (3) Full stack: wget the official docker-compose.yml and run docker-compose up -d for the complete production setup with persistent storage.
3. How is Khoj different from Perplexity AI or ChatGPT?
Perplexity and ChatGPT are cloud-only, stateless, and search the public web. Khoj indexes your private documents on your own machine, retains long-term memory across sessions, and can run 100% offline with local LLMs via Ollama (Llama, DeepSeek, Qwen). You own the data. For intelligent multi-provider LLM routing across your local setup, pair Khoj with Omniroute.
4. Self-hosted vs Khoj Cloud: which should I choose?
- Self-hosted: Full privacy, no data leaves your machine, free to run, requires a server or desktop running 24/7.
- Khoj Cloud (app.khoj.dev): Zero setup, free tier available, but documents are stored on Khoj’s servers.
- Recommendation: Use cloud to evaluate the UX in 10 minutes, then self-host with Docker once you confirm Khoj fits your workflow. For autonomous agent architectures that complement Khoj, see Pi Mono.
Related Architectural Deep Dives
- Pi Mono Explained: Autonomous AI Coding Agent Architecture: Discover how deterministic execution loops and working memory govern autonomous software agents.
- Omniroute: Dynamic LLM Routing & Traffic Management: Route agent queries dynamically across LLM providers to minimize latency and token expenses.
- ADHD Coding Agent: Focus Automation & Multi-Step Memory: Enforce concise, zero-fluff cognitive discipline across Claude Code and Cursor.
Related posts
- AI & Agents
Defuddle: What It Is, Architecture & Web Markdown Extractor Guide
Defuddle by kepano: TypeScript extractor isolating clean Markdown, preserving LaTeX and code blocks - built for Obsidian, RAG pipelines, and LLM ingestion.
9 min readRead → - Developer Tools
Project NOMAD: Offline Knowledge Bunker Architecture & Setup Guide
What is Project NOMAD? Complete guide to the offline knowledge bunker (Crosstalk-Solutions/project-nomad): run local LLMs, Wikipedia, and maps without internet.
5 min readRead → - AI & Agents
OmniRoute: Complete Local AI Gateway Guide for 290+ LLMs & MCP
What is OmniRoute? Guide to the open-source local AI gateway: multiplex 290+ LLMs, stop 429 rate limits with auto-fallback, and native MCP for Claude Code.
16 min readRead → - AI & Agents
LLM & RAG: The 'Smart Librarian' Mental Model
Why do LLMs hallucinate? A mastery guide to Retrieval Augmented Generation (RAG) - the architecture powering every serious AI product in 2026.
5 min readRead →