Defuddle: The Next Generation of Web Content Extraction
Defuddle is a TypeScript alternative to Mozilla Readability built for Obsidian Web Clipper - extracts clean article content with custom site extractors.
TL;DR
Quick Answer Box (Google Search Featured Snippet):
- What is Defuddle? An open-source TypeScript web content extractor developed by
kepano(creator of Obsidian Web Clipper) designed to isolate clean article content from noisy web pages.- How does Defuddle differ from Mozilla Readability? Mozilla Readability uses a single heuristic that frequently mangles code blocks, LaTeX formulas, and modern SPA chats. Defuddle adds an Extractor Registry (
chatgpt.ts,github.ts,reddit.ts) and an Elements pipeline that preserves syntax-highlighted code, LaTeX math, and footnotes for flawless HTML-to-Markdown conversion.- Quick CLI Usage:
npm install -g defuddleand rundefuddle parse <url> --markdown.- Official Repository: kepano/defuddle on GitHub.
Beginner Map: From Messy Webpage to Clean Markdown
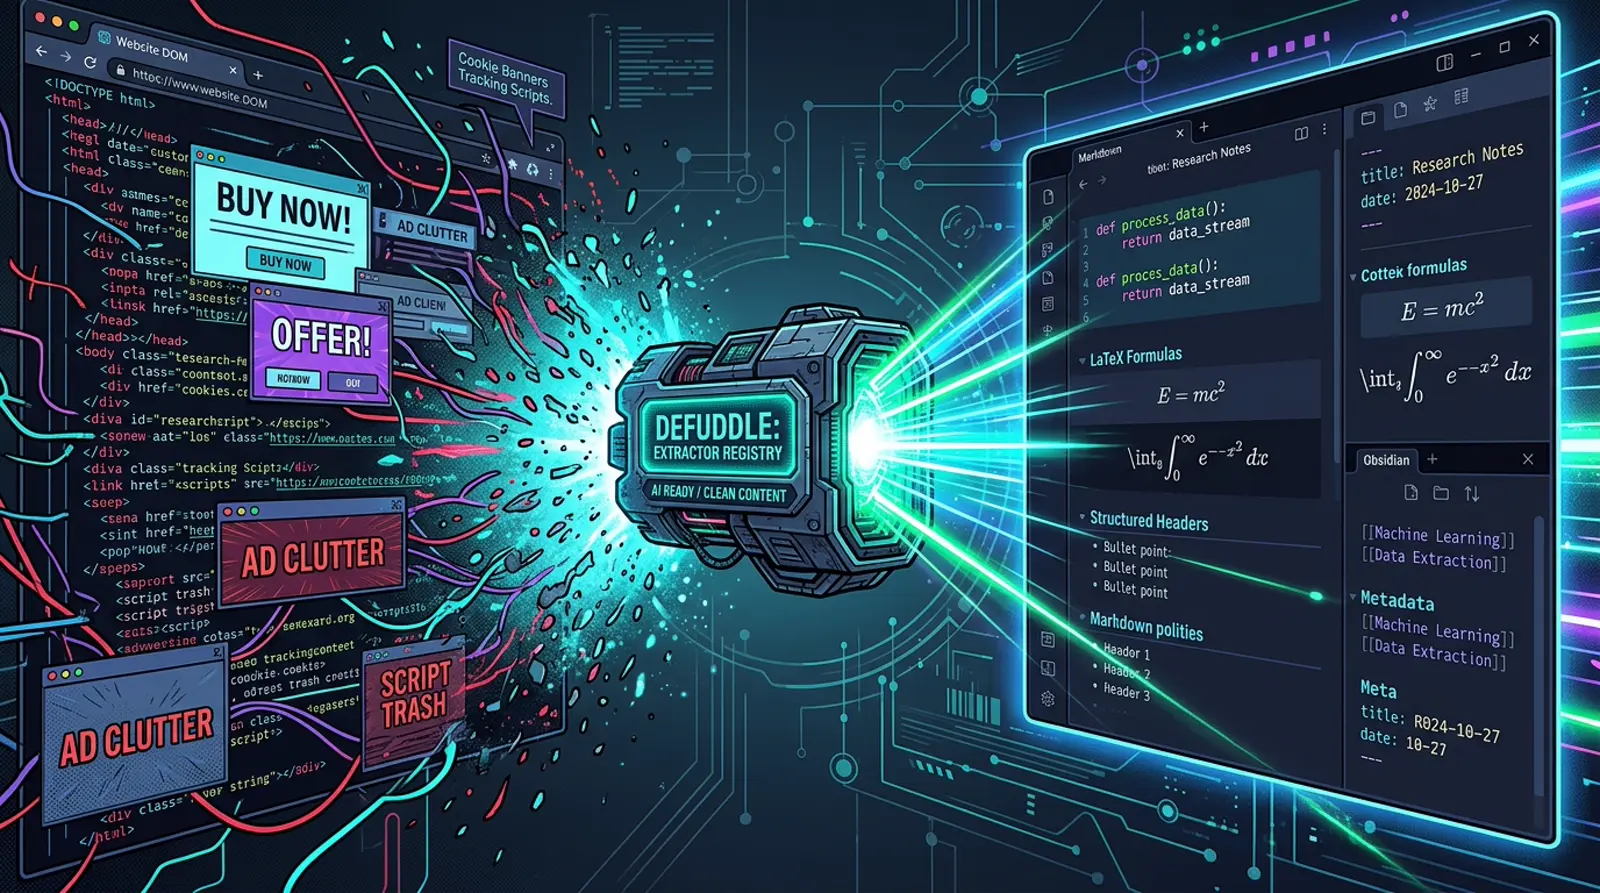
- Input: Cluttered DOM or URL (full of ads, navigation sidebars, and trackers).
- Stage 1 (Extractor Registry): If the site is recognized (
chatgpt.com,github.com,reddit.com), Defuddle triggers an optimized site-specific extractor; otherwise, it runs a heuristic scorer. - Stage 2 (Standardization Pipeline): Cleans code blocks (strips line numbers), parses math into LaTeX, flattens footnotes, and demotes headings.
- Stage 3 (Output): Returns semantic HTML or clean Markdown, ready for Obsidian vaults, vector databases, or LLM context windows. Compare with our offline knowledge bunker on Project Nomad.
Part 1: Foundations - The Mental Model
You have probably used browser “Reader View” extensions, read-it-later apps like Pocket, or web clippers. Under the hood, almost all of them rely on one ancient, legendary library: Mozilla Readability.js.
While Readability is great, the modern web has evolved. Pages now have complex math formulas (MathJax/KaTeX), elaborate code blocks with syntax highlighting, nested footnotes, and JavaScript-rendered content (like X/Twitter or ChatGPT chats). Readability often strips these or outputs messy HTML that is terrible for converting into Markdown.
Enter Defuddle by kepano (the creator of the Obsidian Web Clipper).
Mental Model: Think of Defuddle as Readability 2.0 specialized for Markdown enthusiasts. It is a content extractor that looks at a cluttered web page and surgically isolates the main article, heavily standardizing complex elements (like math, code, and footnotes) into clean, semantic HTML so that subsequent HTML-to-Markdown converters (like Turndown) produce perfect results.
Part 2: The Investigation - Architecture Deep Dive
Defuddle is written purely in TypeScript and designed to run uniformly in the Browser, in Node.js, and via CLI.
The Pipeline Architecture
When you pass a document to Defuddle, it runs the HTML through a multi-stage pipeline:
- Extraction (Site-Specific or Heuristic)
- Standardization (Elements Pipeline)
- Scoring & Cleanup
1. The Extractor Registry
Mozilla Readability applies one giant set of heuristic rules to every site. Defuddle, however, maintains an Extractor Registry (src/extractors/).
If you are parsing a generic blog, it uses heuristics. But if you are parsing a known site, it uses a dedicated extractor. Defuddle ships with built-in extractors for:
- AI Chats:
chatgpt.ts,claude.ts,gemini.ts,grok.ts - Social & Forums:
reddit.ts,hackernews.ts,x-article.ts,twitter.ts - Media & Code:
github.ts,youtube.ts
These extractors know exactly where the payload is on those specific DOM structures, avoiding the need to guess. There is even a useAsync option that falls back to third-party APIs (like FxTwitter) if the local HTML is a blank SPA frame.
2. The Standardization Pipeline
The magic of Defuddle happens in src/elements/. Once the raw content is isolated, Defuddle standardizes it so Markdown converters won’t choke:
- Code Blocks (
code.ts): Checks forpre > code. It strips out line numbers and arbitrary syntax highlighting spans, leaving only semantic<code data-lang="js" class="language-js">tokens. - Math (
math.ts): Detects MathJax, KaTeX, and MathML. It converts them into standardized<math data-latex="...">elements (using libraries likemathml-to-latexandtemmlin the “full” bundle). - Footnotes (
footnotes.ts): Detects various footnote reference patterns (superscripts, brackets) and rewrites them into a standard ordered list at the bottom of the DOM, ensuring Markdown converters create strict[^1]syntax. - Headings (
headings.ts): Demotes H1s to H2s, removes anchor links inside headings, and drops the first heading if it perfectly matches the<title>.
3. Tree Shaking Bundles
Defuddle compiles to three targets:
defuddle/core: Tiny browser bundle. No external dependencies.defuddle/full: Browser bundle that includes heavy MathML/LaTeX parsing libraries.defuddle/node: Optimized for backend scraping using JSDOM.
Part 3: The Diagnosis - What It Does for Developers
For developers building scrapers, AI ingestion pipelines, or productivity tools, Defuddle solves several long-standing headaches.
Problem 1: Ingesting AI Chat Logs
If you try to scrape a ChatGPT or Claude URL using standard Readability, the heavy DOM nesting confuses the heuristic scorer. Defuddle’s specific chatgpt.ts extractor identifies the user/assistant message bubbles and formats them cleanly, making it trivial to dump your chat history into an Obsidian vault or another LLM context window.
Problem 2: Preserving Code and Math
If you clip a technical blog post containing Python code and LaTeX math, standard extractors often destroy the backticks and render math as garbled text. By enforcing the Standardize pipeline, Defuddle ensures that when you pipe its output to Turndown, you get ```python and $$a \neq 0$$.
Example Output
When you run Defuddle, you don’t just get HTML; you get a rich metadata object:
{
  "author": "John Doe",
  "title": "Quantum Computing 101",
  "content": "<article><h2>Introduction</h2>...</article>",
  "description": "A beginner's guide to qubits.",
  "image": "https://example.com/hero.jpg",
  "schemaOrgData": { ... },
  "wordCount": 1250,
  "parseTime": 42
}
Part 4: The Resolution - How to Use Defuddle
You can integrate Defuddle into your stack in minutes.
For Python / CLI Developers (Quick Web Scraping)
If you just want to extract a page via bash quickly:
npm install -g defuddle

# Return a clean JSON payload mapping the site
defuddle parse https://example.com/article --json

# Return pure markdown
defuddle parse https://example.com/article --markdown
For Node.js (Backend Scrapers & AI Pipelines)
If you are writing a data ingestion pipeline or vector-database loader in Node.js (make sure your package.json has "type": "module"):
import { JSDOM } from 'jsdom';
import { Defuddle } from 'defuddle/node';

async function extractArticle(url) {
  // 1. Fetch DOM using JSDOM
  const dom = await JSDOM.fromURL(url);

  // 2. Parse with Defuddle
  const result = await Defuddle(dom, url, {
    markdown: true,
    removeImages: false
  });

  console.log(`Title: ${result.title}`);
  return result.contentMarkdown; // Pure, clean markdown
}
For Browser Extensions (Frontend)
If you are building a React app, Chrome extension, or Web Clipper:
import Defuddle from 'defuddle';

// Pass the live window.document
const extractor = new Defuddle(document, { debug: false });
const payload = extractor.parse();

console.log(payload.content); // Lean, standardized HTML
Final Mental Model
┌────────────────────────────────────────────────────────────┐
│                         Defuddle                           │
│                                                            │
│  "Readability 2.0 engineered for Markdown workflows"       │
│                                                            │
│  How it Extacts:                                           │
│  → Site-specific Extractors (Reddit, ChatGPT, GitHub)      │
│  → Fallback Heuristic Scorer for generic blogs             │
│                                                            │
│  How it Standardizes (The true value):                     │
│  → Code blocks: Strips line numbers, keeps language tags   │
│  → Math: Converts MathJax/KaTeX to semantic MathML/LaTeX   │
│  → Footnotes: Flattens to standardized bottom lists        │
│                                                            │
│  Where it runs:                                            │
│  → Browser (no dependencies)                               │
│  → Node.js (via JSDOM)                                     │
│  → CLI (with built-in --markdown flags)                    │
└────────────────────────────────────────────────────────────┘GitHub: kepano/defuddle
Playground: Defuddle Playground
Defuddle Frequently Asked Questions (FAQ)
1. What is Defuddle and why did kepano create it?
Defuddle is an open-source TypeScript library for extracting clean article content from web pages. Steph Ango (kepano), CEO of Obsidian, created it as the core parsing engine for the official Obsidian Web Clipper. It overcomes the limitations of legacy Mozilla Readability by handling modern web patterns like dynamic single-page applications, code snippets, and mathematical notation.
2. Can Defuddle export directly to Markdown?
Yes. Defuddle has built-in Markdown support when invoked via CLI (defuddle parse <url> --markdown) and in the Node.js bundle via options (markdown: true), utilizing an internal pipeline that converts standardized HTML elements directly into clean, formatted Markdown.
3. How does Defuddle handle math equations and syntax-highlighted code?
Unlike legacy extractors that discard formatting or turn math into unreadable text:
- Math: Detects MathJax, KaTeX, and MathML, converting them into standardized LaTeX format (
$$...$$). - Code: Strips out extraneous line numbers and background spans while preserving the exact language identifier (
data-lang="ts").
4. How can I use Defuddle with LLMs and Vector Databases?
Defuddle acts as a pre-ingestion filter for RAG pipelines. By stripping navigation headers, ads, and cookie banners before passing HTML to text splitters, Defuddle cuts token consumption by 40% to 70% and prevents chunk dilution in vector databases.
Related Web Scraping & AI Data Pipelines
- Project Nomad: Offline Knowledge Bunker Architecture: Learn how to build resilient local knowledge bases and archive critical web documentation offline.
- Ego Lite: Autonomous In-Browser AI Agents: Explore browser automation that operates inside authenticated spaces without being blocked by CAPTCHAs.
- Vector Database & Embeddings Engineering: Master high-density vector storage and clean chunking strategies for enterprise RAG pipelines.
Related posts
What AI DevKit is: a control plane for AI coding agents - and where it stops
An architectural guide to AI DevKit: local-first CLI/TUI console, shared config, SQLite memory, and workflow skills for managing multiple coding agents.
OmniRoute AI Gateway: 290+ LLMs Auto-Fallback, Pricing & Setup Guide
Run OmniRoute 100% locally: multiplex 290+ LLMs, auto-fallback on HTTP 429 rate limits, cut token costs by 15-35%, and native MCP control for Claude Code.
Orca Explained: The AI Orchestrator for Parallel Coding Agents
Orca is an open-source agent IDE that runs multiple coding agents in parallel worktrees, with native terminals, mobile steering, and CLI automation.
Pi Mono Explained: The Anti-Framework for AI Coding Agents
Pi Mono is a radically extensible AI agent monorepo that refuses to dictate your workflow, stack, or agent framework of choice.